Tag: network

  • Fixing Weak SSH Ciphers On a Cisco ASAv

    Fixing Weak SSH Ciphers On a Cisco ASAv

    By default the Cisco ASAv has weak ssh config that many modern OS’s do not support.

    ssh admin@10.1.10.56
    Unable to negotiate with 10.1.10.56 port 22: no matching host key type found. Their offer: ssh-rsa
    

    This error is from the client side ssh client refusing to use any of the host key algorithms that are offered by the ASAv.

    To get around this you can try the following.

    ssh -o HostKeyAlgorithms=+ssh-rsa 
    -o PubkeyAcceptedAlgorithms=+ssh-rsa
    admin@10.1.10.56
    The authenticity of host '10.1.10.56 (10.1.10.56)' can't be established.
    RSA key fingerprint is SHA256:TIbF/exW4uqfmy/yf8JyxddX8DApYduK2NVXNHfRBXI.
    This key is not known by any other names.
    Are you sure you want to continue connecting (yes/no/[fingerprint])? yes
    Warning: Permanently added '10.1.10.56' (RSA) to the list of known hosts.
    ssh_dispatch_run_fatal: Connection to 10.1.10.56 port 22: error in libcrypto

    However as you can see from the above output there is another error. This error is also from the client side OS, as its enforcing its own crypto policy.

    One way around this is to enable legacy crypto on the OS side. Which you can do via the command below.

    sudo update-crypto-policies --set LEGACY
    

    However, this is a bad idea and can screw up a lot of other things on the client side. Rather than work around this we will fix.


    Fix SSH on the Cisco ASAv – Instead of Breaking my Workstation

    Cisco documents that starting in ASA 9.16(1), the ASAv added support for EDDSA and ECDSA SSH host keys, and the ASAv will prefer EDDSA → ECDSA → RSA if those keys exist.

    Given I’m on ASAv 9.20(4), I should be able to generate these keys and then connect with my normal ssh client settings. See commands below.

    enable
    configure terminal
    
    ! Generate an Ed25519 (EdDSA) host key (preferred)
    crypto key generate eddsa edwards-curve ed25519
    
    ! Also generate an ECDSA host key (good fallback)
    crypto key generate ecdsa elliptic-curve 256
    
    write memory
    

    Restarting SSH on the ASAv

    Now we need to restart SSH on the ASAv to switch the host key used by SSH. You will need to run these commands from the console.

    conf t
    no ssh 0.0.0.0 0.0.0.0 management
    ssh 0.0.0.0 0.0.0.0 management
    end

    Now we can verify that keys in use on the ASAv. Specifically we want to look at the EDDSA and ECDSA .

    # show crypto key mypubkey ecdsa
    # show crypto key mypubkey eddsa

    Now we can login normally via SSH from our Workstation

     ssh admin@10.1.10.56
    The authenticity of host '10.1.10.56 (10.1.10.56)' can't be established.
    ECDSA key fingerprint is SHA256:Z5+PHzIl6L9BvvdYl2bBrFGi2rlmefmuv0uc27UTBo4.
    This key is not known by any other names.
    Are you sure you want to continue connecting (yes/no/[fingerprint])? yes
    Warning: Permanently added '10.1.10.56' (ECDSA) to the list of known hosts.
    admin@10.1.10.56's password: 
    User admin logged in to ciscoasa
    Logins over the last 1 days: 1.  
    Failed logins since the last login: 0.  
    Type help or '?' for a list of available commands.
    ciscoasa> 
    

    Further Configuration for SSH on the ASAv

    I did find that after all my changes to SSH on the ASAv, I was still unable to ssh to the asav from several VMs (new RHEL10 build for example).

    ssh admin@10.1.10.56
    kex_exchange_identification: read: Connection reset by peer

    In order to get ssh to work from RHEL 10, I ran the commands below on the ASAv

    conf t
    ssh key-exchange group dh-group14-sha256
    ssh key-exchange group curve25519-sha256

    Details below as to why this was required.

    Command AddedWhy RHEL 10 liked it
    dh-group14-sha256This moves the hashing from SHA-1 to SHA-256. RHEL 10 requires SHA-256 or higher for the handshake to be considered “safe.”
    curve25519-sha256This is the preferred algorithm for modern OpenSSH. It is extremely fast and mathematically robust. Once the ASA offered this, RHEL 10 stopped looking for other options and just connected.

  • CEPH: TCP Performance Tuning

    ethernet-cable-fade

    Below are a few TCP tunables that I ran into when looking into TCP performance tuning for CEPH.

    Note that there are two separate sections for 10GE connectivity, so you will want to test with both to find what works best for your environment.

    To implement, we just add what is below to /etc/sysctl.d/99-sysctl.conf and run “sysctl -p“. Changes are persistent across reboots. Ideally these TCP tunables should be deployed to all CEPH nodes (OSD most importantly).

    [code language=”css”]
    ## Increase Linux autotuning TCP buffer limits
    ## Set max to 16MB (16777216) for 1GE
    ## 32MB (33554432) or 54MB (56623104) for 10GE

    # 1GE/16MB (16777216)
    #net.core.rmem_max = 16777216
    #net.core.wmem_max = 16777216
    #net.core.rmem_default = 16777216
    #net.core.wmem_default = 16777216
    #net.core.optmem_max = 40960
    #net.ipv4.tcp_rmem = 4096 87380 16777216
    #net.ipv4.tcp_wmem = 4096 65536 16777216

    # 10GE/32MB (33554432)
    #net.core.rmem_max = 33554432
    #net.core.wmem_max = 33554432
    #net.core.rmem_default = 33554432
    #net.core.wmem_default = 33554432
    #net.core.optmem_max = 40960
    #net.ipv4.tcp_rmem = 4096 87380 33554432
    #net.ipv4.tcp_wmem = 4096 65536 33554432

    # 10GB/54MB (56623104)
    net.core.rmem_max = 56623104
    net.core.wmem_max = 56623104
    net.core.rmem_default = 56623104
    net.core.wmem_default = 56623104
    net.core.optmem_max = 40960
    net.ipv4.tcp_rmem = 4096 87380 56623104
    net.ipv4.tcp_wmem = 4096 65536 56623104

    ## Increase number of incoming connections. The value can be raised to bursts of request, default is 128
    net.core.somaxconn = 1024

    ## Increase number of incoming connections backlog, default is 1000
    net.core.netdev_max_backlog = 50000

    ## Maximum number of remembered connection requests, default is 128
    net.ipv4.tcp_max_syn_backlog = 30000

    ## Increase the tcp-time-wait buckets pool size to prevent simple DOS attacks, default is 8192
    net.ipv4.tcp_max_tw_buckets = 2000000

    # Recycle and Reuse TIME_WAIT sockets faster, default is 0 for both
    net.ipv4.tcp_tw_recycle = 1
    net.ipv4.tcp_tw_reuse = 1

    ## Decrease TIME_WAIT seconds, default is 30 seconds
    net.ipv4.tcp_fin_timeout = 10

    ## Tells the system whether it should start at the default window size only for TCP connections
    ## that have been idle for too long, default is 1
    net.ipv4.tcp_slow_start_after_idle = 0

    #If your servers talk UDP, also up these limits, default is 4096
    net.ipv4.udp_rmem_min = 8192
    net.ipv4.udp_wmem_min = 8192

    ## Disable source redirects
    ## Default is 1
    net.ipv4.conf.all.send_redirects = 0
    net.ipv4.conf.all.accept_redirects = 0

    ## Disable source routing, default is 0
    net.ipv4.conf.all.accept_source_route = 0
    [/code]

    Reference here

  • How to Create Non-Routable Isolated (but not Private) Vlans on a Cisco Catalyst Layer 3 Switch

    data_sheet_c78-530976-1

    First off let’s start out by saying that Isolated VLANs and Private VLANs are two completely different things… they are not at all the same. To a network administrator, this should make perfect sense. However, a Server or Virtualization Administrator may or may not know the different. Because of this, I hear many non-network Administrators toss around the term “Private VLAN“, when they actually mean to say “Isolated Vlan“, or more specifically what they are referring to is a “Non-Routable” VLAN.

    What’s confusing is that the networks that we plan to use over our newly commissioned Non-Routable VLANs can correctly be refereed to as Private networks. They are private because no traffic can get in our out without a direct lP link to this network. However the VLANs themselves are not private, just isolated, or non-routable.

    I believe that you can see where the confusion comes from.

    So allow me to provide a bit of context before we go any further.

    In my specific case, I need to create what are commonly (however incorrectly) referred to as Private VLANs to act as a back-end network for an OpenStack deployment. I cannot tell you how often I have heard someone make this mistake. This new VLAN, or network, needs to remain isolated from the outside world, meaning that it does not need to be able to route to any other network, or out to the internet. Rather, this new VLAN needs to send isolated traffic back and forth between network nodes deployed as part of my OpenStack Deployment. What I am describing here is not a “Private VLAN”, it is a “Non-Routable”, or “Isolated VLAN”

    So please let’s make sure that we are using the correct terms.

    So here is how you do it.

    In my case I want to create two isolated VLANS for isolated traffic between my OpenStack nodes. Note that I am using nested virtualization, so my OpenStack nodes are themselves VMs.

    First lets create what I will refer to as NR-1 (non-routable-1). We will use the VLAN id 666 as its easy to remember.

    s3560#conf t
    Enter configuration commands, one per line. End with CNTL/Z.
    s3560(config)#vlan 666
    s3560(config-vlan)#name NR-1
    s3560(config-vlan)#end

    Now lets create what I will refer to as NR-2. (non-routable-2)

    s3560#conf t
    Enter configuration commands, one per line. End with CNTL/Z.
    s3560(config)#vlan 667
    s3560(config-vlan)#name NR-2
    s3560(config-vlan)#end

    How lets check out our vlans, starting with 666

    s3560#show vlan id 666

    VLAN Name Status Ports
    —- ——————————– ——— ——————————-
    666 NR-1 active

    …trunc…

    Now let’s take a look at 667

    s3560#show vlan id 667

    VLAN Name Status Ports
    —- ——————————– ——— ——————————-
    667 NR-2 active

    …trunc…

    Note, that if I wanted to make these VLANs routable, I would need to add a layer3 interface. We are obviously not going to do that here.

    Now lets add these new VLANs to our existing virtualization server trunks. We are going to do this to a range of interfaces to save time. Note that I was already allowing VLANS 101-104 and 192 on these trunks.

    s3560#conf t
    Enter configuration commands, one per line. End with CNTL/Z.
    s3560(config)#interface range GigabitEthernet0/15 -18
    s3560(config-if-range)#switchport trunk allowed vlan 101-104,192,666,667
    s3560(config-if-range)#end

    Now don’t forget to save our config.

    s3560#copy run start
    Destination filename [startup-config]?
    Building configuration…
    [OK]
    0 bytes copied in 1.443 secs (0 bytes/sec)

  • Configure Syslog Logging Levels on the Asus RT-AC66U Router

    4614_WizardStressToy_1


    So here is a quick little one that I figured out the other day.

    Having just set up a Splunk server at home, I wanted to make sure that I was not going to hit the data limit of 500mb a day for the free version of Splunk. I figured out pretty fast that my ASUS RT-AC66U was a very chatty-cathy when it came to syslog… sending me all sorts of very raw data that I was, at least at first, not so sure I was interested in indexing. So I hit the cli and started poking around.

    First off, before we jump in, let’s make sure that we are all on the same page. First thing to note is that I am running the custom Merlin firmware, however that doubt that the stock firmware is much different. Second, let’s make sure that we all know how to configure syslog on our Asus.

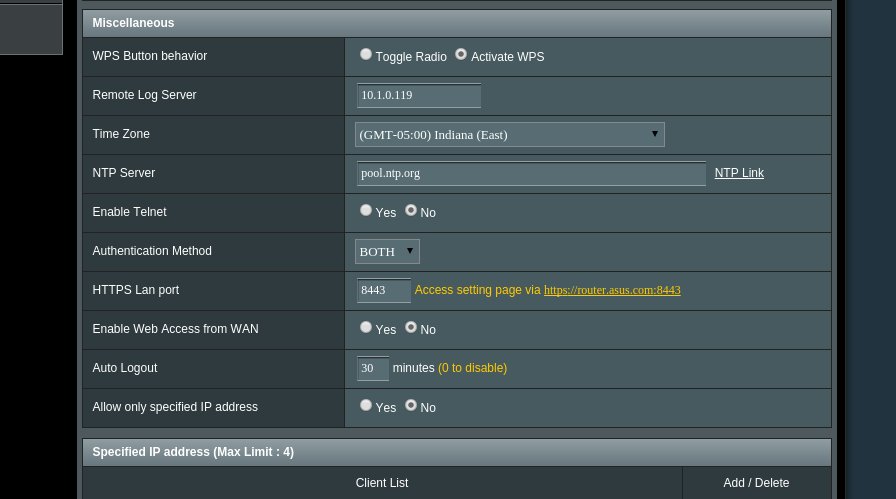
    To setup forwarding syslog to a remote syslog server, you first client on “Administration” in the “Advanced Settings” panel on the left. Then select the “System” tab near the top of the page. Scroll down to “Miscellaneous”. This section is shown below. Enter the IP address of your syslog server (or Splunk server in this case) in the “Remote Log Server” field.

    syslog_asus

    Now lets get down to the business of adjusting our logging level. First you need to ssh into your router.

    Note that it appears that by default the log level is set to 7.

    admin@RT-AC66U: # nvram show | grep log_level
    log_level=7

    Now before you get too excited, I am actually not sure that the main log level adheres to rfc5424. I have yet to find any published documentation from Asus to confirm this. However, according to this guy’s blog, this configuration might be a bit less chatty. Note that there are a few additional settings here which you can play around with. With these settings, I am assuming that 1 is on, and 0 if off. I am still experimenting.

    admin@RT-AC66U: # nvram set log_level=2
    admin@RT-AC66U: # nvram set log_enable=1
    admin@RT-AC66U: # nvram set log_rejected=1
    admin@RT-AC66U: # nvram set log_dropped=1
    admin@RT-AC66U: # nvram set log_accepted=0

    Now lets save our change and reboot

    admin@RT-AC66U: # nvram commit
    admin@RT-AC66U: # reboot

    Note that there also is a vpn_loglevel=3 setting that can be configured via nvram. This setting might be useful to those running a VPN server on their router.

  • Redhat 6 Minimal Kickstart Configuration with VMware Tools and Puppet Agent Install

    smartaHere is my small, crude, little Kickstart configuration and post install script that I have up and running in my lab at home. Don’t expect to find anything too fancy here, as this Kickstart was purposefully built to be small and to the point. Here, the point was to spin up a VM, run through a basic install of CentOS/Redhat Linux,  and install VMware Tools along with a Puppet agent.

    Note that this post assumes that you have a working Kickstart server.

    First lets take a look at our kickstart file, CentOS-6.6-x86_64-minimal.ks

    The section directly below kicks off our kickstart ks file. Here we set our root password (no that’s not my hash) and setup our network interface for DHCP. We do a tiny bit of disk partitioning, and setup very simple LVM. Then we choose our packages. As you can see my package list is not at all fancy, I just want to make sure that I have pretty much every package that might need for a lab VM.

    [code language=”bash”]
    # Kickstart file for RHEL 6 Minimal
    # Small Disk

    text
    install
    url –url=http://10.1.0.106/ks/loop/CentOS-6.6-x86_64-bin-DVD1
    lang en_US.UTF-8
    keyboard us
    network –onboot yes –device eth0 –bootproto dhcp –noipv6
    rootpw –iscrypted $6$X/4YYZPN$4Sv.khxXms8N8vRssR/Vl35w/m80FF5P6p7aX0D7EFfD9p734F6tU4kXdcSCoOjPiXLrVxqfKxxxxxxxxxxxq5551
    firewall –disabled
    authconfig –enableshadow –passalgo=sha512
    selinux –permissive
    timezone America/New_York

    # Disk
    bootloader –location=mbr –driveorder=sda –append="crashkernel=auto rhgb"
    zerombr
    clearpart –all –drives=sda
    part pv.1 –grow –size=1
    part /boot –fstype=ext4 –size=1024
    volgroup VolGroup pv.1
    logvol / –fstype=ext4 –name=lv_root –vgname=VolGroup –size=1024 –grow
    logvol swap –name=lv_swap –vgname=VolGroup –size=1024

    #Network
    network –device=eth0 –bootproto=dhcp –nameserver=10.1.0.110

    # Package Selection
    %packages –nobase –excludedocs
    @Base
    @core
    kernel-headers
    wget
    perl
    sysstat
    bind-utils
    tcpdump
    [/code]

    Now let me pause to point out the section below. This is the %pre script that I am using to prompt me for the VM hostname before the install begins. The hostname needs to be set before you install puppet on the VM, otherwise you are going to have to recreate your puppet certificates after you set properly set your hostname post install and reboot.

    [code language=”bash”]
    %pre –log=/root/ks_pre.log
    #change to tty6 to get input
    chvt 6
    exec </dev/tty6 > /dev/tty6

    #Prompt for hostname
    echo "What is my hostname?"
    read NAME
    echo "NETWORKING=yes
    HOSTNAME=${NAME}" > network
    chvt 1
    [/code]

    Now we run a simple post install, along with a custom post install script. It is this script that will install Vmware tools and Puppet. Myself, I prefer keeping most of my code out of the actual Kickstart ks file, however you can always jam all your code into it if you like. You will just need to validate your syntax first, as I have not tested my config this way.

    [code language=”bash”]
    %post –nochroot
    # bring in hostname collected from %pre, then source it
    cp network /mnt/sysimage/etc/sysconfig/network
    . /mnt/sysimage/etc/sysconfig/network
    # force hostname change
    /mnt/sysimage/bin/hostname $HOSTNAME
    #Post Install
    %post –log=/root/ks-post.log
    cd /root
    echo "Getting the post install script – if this takes a long time check network or path"
    wget http://10.1.0.106/ks/scripts/centos-6-postinstall.bash
    echo "Running the post install script"
    /bin/bash centos-6-postinstall.bash
    [/code]

    Ok, so below is the post install script that I am calling in the section above. After a quick modification of my hosts file, I pull down the Puppet installer from my local Puppet server. Next we install the open source VMware tools packages, after creating the required yum repofile.


    [code language=”bash”]
    #!/bin/bash
    #centos-6-postinstall.bash

    #Switch to the 6th console and redirect all i/o
    exec < /dev/tty6 > /dev/tty6 2> /dev/tty6
    chvt 6

    # Lets make sure we know who the puppet server is before we get too far
    echo "Adding hosts entry for puppet master"
    echo "10.1.0.115 puppet puppet.lab.localdomain" >> /etc/hosts

    ## Update Via Yum – not doing this for now in order to save time
    #yum -y update
    # Install puppet from local puppet master
    echo "Downloading and running Puppet installer"
    curl -k https://10.1.0.115:8140/packages/current/install.bash | sudo bash
    #Install Open Source VMware Tools
    rpm –import http://packages.vmware.com/tools/keys/VMWARE-PACKAGING-GPG-DSA-KEY.pub
    rpm –import http://packages.vmware.com/tools/keys/VMWARE-PACKAGING-GPG-RSA-KEY.pub

    echo -e "[vmware-tools]\nname=VMware Tools\nbaseurl=http://packages.vmware.com/tools/esx/5.1latest/rhel6/$HOSTTYPE\nenabled=1\ngpgcheck=1" > /etc/yum.repos.d/vmware-tools.repo

    echo "Installing Vmware Tools"
    yum -y install vmware-tools-esx-nox

    #Minor grub.conf modifications
    sed -i ‘s/rhgb quiet//’ /boot/grub/grub.conf
    sed -i ‘s/hiddenmenu//’ /boot/grub/grub.conf
    sed -i ‘s/timeout=5/timeout=10/’ /boot/grub/grub.conf

    #Kick off first puppet run, for some reason I think you might need to do this twice.
    sleep 5
    echo "Running Puppet for the first time"
    puppet agent –test
    puppet agent –test

    #Tell us we have reached the end
    echo "We have reached the end of the post-install script"
    [/code]

    A couple of additional details to note about the post install script above. I like to modify the grub.conf so that I unhide the menu and increase the time out. I also like to make sure that we disable the Redhat graphical boot screen… I want to make sure its easy to catch any errors or miss-configurations in my kickstarts.
     

  • Vmware CapacityIQ Unregister a Vcenter Server via the CLI

    Vmware-logoOk two in a row, now thats strange. Anyway.. I was working on a rebuild and re-ip of my Vcenter Server as I was in the process of changing over to the Vcenter appliance, when i realized that I was going to have to lay hands on a lot of tools and change them to point/connect to my new Vcenter Server instance. Anyway. I started of with VCOPS, and I was surprisingly sucessful. So I figured I would move on to Capacity IQ.

    Again, being the Linux guy that I am, I hit up the cli and stated fiddling around. I stumbled across the ciq-admin command and was able to find the following

    [ciqadmin@ciq ~]$ ciq-admin register status
    vCenter Server Registration Status = Registered
    vCenter Server address             = https://vc00.lab.localdomain/sdk
    vCenter Server user                = LAB\user


    Hey ok, that looks good so far. Lets see if we can unregister.

    [ciqadmin@ciq ~]$ ciq-admin unregister
    Connection to VC failed. Disconnected CIQ, but could not remove CIQ extension from VC.


    Well crap, you will never be able to connect to my original Vcenter Server… it's dead and its not coming back. Luckily it appears that we can force the registration of a new Vcenter Server

    [ciqadmin@ciq ~]$ ciq-admin  register –vc-server vc01.lab.localdomain –force  –user root –password mypasswd
    Stopping CIQ :                                             [  OK  ]
    Starting CIQ :                                             [  OK  ]
    ciq-watchdog is now enabled


    Now head back on over and get a gander at the webUI. Still shows the old Vcenter Server? Just logout and log back in again and life should be good.

     
    Related articles

    Vmware VCenter Virtual Appliance – Death to Windows.. I think.
    ESX 5: How to Power On A Virtual Machine from the Command Line
    VMware vCenter Operations Manager Essentials – Introduction to vCenter Operations Manager
    vCenter Operations Manager: VMware's move into cloud monitoring?
  • Vmware Vcenter Operations Manager Unregister a Vcenter Server via the CLI

    Vmware-workstation-17-535x535So my Windows based Vmware Vcenter Server went belly up again. Something to do with the SSO database not starting. Not being a lover of Windows I decided to give the Vcenter Server Appliance a shot. Install was great and I am kicking myself a bit as to why I spent so much time fighting with Windows. My new Vcenter Server, which has a different IP address then the original Windows box (might make a great Veeam server) was not registered with Vcenter Operations Manager. I was not prepared to reinstall that thing again. So I needed to figure out how to manually unregister a Vcenter instance and add register another one in its place.

    Since VCOPs runs Linux, I decided to ssh into the server and see if I could figure it out. First thing I found that I needed to do was figure out the registered Vcenter Server name and Vcenter Name (whatever that’s supposed to be) I was able to do this using the vcops-admin command.

    admin@vcops:~> vcops-admin summary


    This command output a bunch of stuff, but the important bits for this task are below.

    Registration Details
    --------------------
    vCenter Server address  = https://vc00.lab.localdomain/sdk
    vCenter Server name = Lab Vcenter


    So now we need to unregister the sucker above. Note that this command takes a bit to unregister

    admin@vcops:~> vcops-admin unregister --vc-name Lab\ Vcenter --vc-server https://vc00.lab.localdomain/sdk --user LAB\\userid --password mypassword--force
    vCenter Server unregister = success


    So flip on over to your browser and log in. The unregister process will cause the webUI to reload, so if you were already logged in you will find that you still need to log in again.

    Now you can register your new Vcenter Server via the webUI.
    Related articles

    Vmware VCenter Virtual Appliance – Death to Windows.. I think.
    ESX 5: How to Power On A Virtual Machine from the Command Line
    vCenter Operations Manager: VMware’s move into cloud monitoring?
    VCOPs – VMware’s Move into Cloud Monitoring